Comparing the Xilinx MIG with an Open Source DDR3 Controller
Comparing the Xilinx MIG with an open source DDR3 controller
Last year, I had the wonderful opportunity of mentoring Angelo as he built an open source DDR3 SDRAM controller .
Today, I have the opportunity to compare this controller with AMD (Xilinx)’s Memory Interface Generator (MIG) solution to the same problem. Let’s take a look to see which one is faster, better, and/or cheaper.
Design differences
Before diving into the comparison, it’s worth understanding a bit about DDR3–both how it works, and how that impacts its performance. From there, I’d like to briefly discuss some of the major design differences between Xilinx’s MIG and the UberDDR3 controller .
We’ll start with the requirements of an SDRAM controller in general.
SDRAM in general
SDRAM stands for Synchronous Dynamic Random Access Memory . “Synchronous” in this context simply means the interface requires a clock, and that all interactions are synchronized to that clock. “Random Access” means that you should be able to access the memory in any order you wish. The key word in this acronymn, though, is the “D” for Dynamic.
“Dynamic” RAM is made from capacitors, rather than flip flops. Why? Capacitors can be made much smaller than flip flops. They also use much less energy than flip flops. When the capacitor is charged, the “bit” of memory it represents contains a “1”. When it isn’t, the bit is a zero. There’s just one critical problem: Capacitors lose their charge over time. This means that every capacitor in memory must be read and recharged periodically or it will lose its contents. The memory controller is responsible for making sure this happens by issuing “refresh” commands to the memory.
That’s only the first challenge. Let’s now go back to that “synchronous” part.
The original (non-DDR) SDRAM standard had a single clock to it. The controller would generate that clock and send it to the memory to control all interactions.
This was soon not fast enough. Why not send memory values on both edges of the clock, instead of just one? You might then push twice as much data across the interface for the same I/O bandwidth. Sadly, as you increase the speed, pretty soon the data from the memory doesn’t come back synchronous to the clock you send. Both the traces on your circuit board, as well as the time to complete the operation within the memory chip will delay the return signals so much that the returned data no longer arrives in time to be sampled at the source by the source’s clock before the next clock edge. Worse, these variabilities are somewhat unpredictable. Therefore, memories were modified so that they return a clock together with the data–keeping the data synchronous with the clock it is traveling with.
Sampling data on a returned clock can be a challenge for an FPGA. Worse, the returned clock is discontinuous: it is only active when the memory has data to return. This will haunt us later, so we’ll come back to it in a moment.
For now, let’s go back to the “dynamic” part of an SDRAM.
SDRAMs are organized into banks, with each bank of memory being organized into rows of capacitors. To read from an SDRAM, a “row” of data from a particular memory bank must first be “activated.” That is, it needs to be copied from its row of capacitors into a row of flip flops. From here, “columns” within this row can be read or written as desired. However, only one row of memory per bank can be active at any given time. Therefore, in order to access a second row of memory, the row in use must first be copied back to its capacitors. This is called “precharging” the row. Only then can the desired row or memory be copied to the active row of flip-flops for access.
I mentioned SDRAM’s are organized in “banks”. Each of these “bank”s can controlled independently. They each have their own row of active flip-flops. With few exceptions, such as the “precharge all rows” command, or the “refresh” cycle command, most of the commands given to the memory will be bank specific.
Hence, to read a byte of memory, the controller must first identify which bank the byte of memory belongs to, and from there it must identify which row is to be read. The controller must then check which row is currently in the flip-flop buffer for that bank (i.e. which row is active). If a different row is active, that row must first be precharged. If no row is active, or alternatively once a formerly active row is precharged, the controller may then activate the desired row. Only once the desired row is active can the controller issue a command to actually read the desired byte from the row. Oh, and … all of this is contingent on not needing to refresh the memory. If a refresh interrupt takes place, you have to precharge all banks, refresh the memory, and then start over.
Well, almost. There’s another important detail: Because of the high speeds we are talking about, the memory will return data in bursts of eight bytes. Hence, you can’t read just a single byte. The minimum read quantity is eight bytes in a single “byte lane”.
What if eight bytes at a time isn’t enough throughput for you? Well, you could strap multiple memory chips together in parallel. In this case, every command issued by the controller would be sent to all of the memory chips. All of them would activate rows together, all of them would refresh their memory together, and all of them could read eight bytes at a time. Each of these chips, then, would control a single “byte lane”. In our case today, we’ll be using a memory having eight “byte lanes”.
So, when it comes to the performance of a memory controller, what do we want to know? We want to know how long it will take us from when the controller receives a read (or write) request until the data can be returned from the memory chip. This includes waiting for any (potential) refresh cycles, waiting for prior active rows to be recharged, new rows to be activated, and the data to finally be returned. The data path is complex enough that we’ll need to be looking at these times statistically.
Specifically, we’re going to model transaction time as some amount of per-transaction latency, followed by a per-amount throughput.
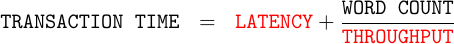
Our goal will be to determine these two unknown quantities: latency and throughput . If we do our job well, these two numbers will then help us predict answers to such questions as: how long will a particular algorithm take, and how much memory bandwidth is available to an application.
Let’s now discuss some of AMD (Xilinx)’s DDR3 memory controller This is the controller generated by their “Memory Interface Generator” and affectionately known simply as the “MIG” or “MIG controller”.
AMD (Xilinx)’s MIG controller is now many years old. Judging by their change log, it was first released in 2013. Other than configuration adjustments, it has not been significantly modified since 2016. This is considered one of their more “stable” IPs. It gets a lot of use by a wide variety of users, and I’ve certainly used it on a large number of projects.
Examining the source code of the MIG reveals that it is built in two parts. This can be seen from Fig. 1 below, which shows how the MIG fits in the context of the entire test stack we’ll be using today.
The first part of the MIG processes AXI transaction requests into its internal “native” interface. AXI, however, is a complex protocol. This translation is not instantaneous, and therefore takes a clock (or two) to accomplish. Many FPGA designers have discovered they can often improve upon the performance of the MIG by skipping this AXI translation layer and using the “native” interface instead. I have not done so personally, since I haven’t found sufficient documentation of this “native” interface to satisfy my needs–but perhaps I just need to look harder at what’s there.
One key feature of an AXI interface is that it permits a certain amount of transaction reordering. For example, a memory controller might prioritize two interactions to the same bank of memory, such that the interaction using the currently active row might go first. Whether or not Xilinx’s MIG does this I cannot say. For today’s test measurements, we’ll only be using one channel–whether read or write, and we’ll only be using a single AXI ID. As a result, all requests must complete in order, and there will be no opportunity for the MIG to reorder any requests.
DDR3 speeds also tend to be much faster than the FPGA logic the controller must support. For this reason, Xilinx’s DDR3 controller runs at either 1/2 or 1/4 the speed of the interface. This means that, on any given FPGA clock cycle, either two or four commands may be issued of the DDR3 device. For this test, we’ll be running at 1/4 speed, so four commands may be issued per system clock cycle.
The biggest problem Xilinx needed to solve with their controller was how to sample return data. Remember, the data returned by the memory contains a discontinuous clock. Worse, the discontinuous clock transitions when the data transitions. This means that the controller must (typically) delay the return clock by a quarter cycle, and only then clock the data on the edge. But … how do you know how far a quarter cycle delay is in order to generate the correct sample time for each byte lane?
Xilinx solved this problem by using a set of IO primitives that they’ve never fully documented. These include PHASORs and IO FIFOs. Using these IO primitives, they can lock a PLL to the returned data clock, and then use that PLL to control the sample time of the return data. This clock is then used to control a special purpose asynchronous FIFO. From here, the data is returned to its environment.
One unusual detail I’ve seen from the MIG is that it will often stall my read requests for a single cycle at a time in a periodic fashion. Such stalls are much too short for any refresh cycles. They are also more frequent than the (more extended) refresh cycles. This leads me to believe that Xilinx’s IO PLL primitive has an additional requirement, which is that in order to maintain lock, the MIG must periodically read from the DDR3 SDRAM. Hence, the MIG must not only take the memory offline periodically to keep the capacitors refreshed, it must also read from the memory to keep this IO PLL locked. Worse, it cannot read from the device at the same time it does this station keeping. As with the AXI to native conversion, this PLL station keeping requirement negatively impacts the MIG’s performance.
Before leaving this point, let me underscore that these “special purpose” IO elements were never fully documented. This adds to the challenge of building an open source controller, since the open source engineer must either reverse engineer these undocumented hardware components or build their data sampler in some other fashion.
Some time ago, I tried building a block-RAM based memory peripheral capable of handling AXI exclusive access requests . While trying to verify that the ZipCPU could generate exclusive access requests and that it would do so properly, I looked into whether or not the MIG would support them. Much to my surprise, the MIG has no exclusive access capability . I’ve since been told that this isn’t a big deal, since you only need exclusive access when more than one CPU is running on the same bus and the MicroBlaze CPU was never certified for multi–core operation, but I do still find this significant.
Finally, the MIG controller tries to maximize parallelism with various “bank machines”. These “bank machines” appear to be complex structures, allocated dynamically upon request. Each bank machine is responsible for handling when and if a row for a given memory bank must be activated, read, written, or precharged. While most memories physically have eight banks, Xilinx’s MIG permits a user to have fewer bank machines. Hence, the first step in responding to a user request is to allocate a bank machine to the request. According to Xilinx, “The [MIG] controller implements an aggressive precharge policy.” As a result, once the request is complete, the controller will precharge the bank if no further requests are pending. The unfortunate consequence of this decision is that subsequent accesses to the same memory will need to first activate the row again before it can be used.
This leads us to the UberDDR3 controller .
The UberDDR3 controller is an open source (GPLv3) DDR3 controller. It was not built with AMD (Xilinx) funding or help. As such, it uses no special purpose IO features. Instead, it uses basic ISERDES/OSERDES and IDELAY/ODELAY primitives. As a result, there are no PHASER_IN s, PHASER_OUT s, IN_FIFO s OUT_FIFO s, or BUFIO s.
This leads to the question of how to deal with the return clock sampling from the DDR3 device. In the case of the UberDDR3 controller , we made the assumption that the DQS toggling would always come back after a fixed amount of time from the clock containing the request. A small calibration state machine is used to determine this delay time and then to find the center of the “eye”. Once done, IDELAY elements, coupled with a shift register, are then used to get the sample point.
Fig. 2 shows a reference to this process.
It is possible that this method will lose calibration over time. Indeed, even the MIG wants to use the XADC to watch for temperature changes to know if it needs to adjust its calibration. Rather than require the XADC, the UberDDR3 controller supports a user input to send it back into calibration mode. Practically, I haven’t needed to do this, but this may also be because my test durations weren’t long enough.
Another difference between the UberDDR3 controller and the MIG is that the UberDDR3 controller only has one interface: Wishbone B4 (Pipelined) . This interface is robust enough to replace the need for the MIG’s non-standard “native” interface. Further, because Wishbone has only a single channel for both reads and writes, the UberDDR3 controller maintains a strict on all transactions. There’s no opportunity for reordering accesses, and no associated complexity involved with it either.
This will make our testing a touch more difficult, however, because we’ll be issuing Wishbone requests–native to the UberDDR3 controller but not the MIG. A simple bridge , costing a single clock cycle, will convert from Wishbone to AXI prior to the MIG. We’ll need to account for this when we get to testing.
The UberDDR3 controller also differs in how it handles memory banks. Rather than using an “aggressive” precharging strategy, it uses a lazy one. Rows are only precharged (returned back to the capacitors) when 1) the row has been active too long, or 2) when it is time to do a refresh, and so all active rows on all banks must be precharged. This works great under the assumption that the next access is most likely to be in the vincinity of the last one.
A second difference in how the UberDDR3 controller handles memory banks is that, unlike the MIG, the bank address is drawn from the bits between the row and column address, as shown in Fig. 3.
Although the MIG has an option to do this, it isn’t clear that the MIG takes any advantage of this arrangement. The UberDDR3 controller , on the other hand, was designed to take explicit advantage of this arrangement. Specifically, the UberDDR3 controller assumes most accesses will be sequential through memory. Hence, when it gets a request for a memory access that is most of the way through the column space of a given row, it then activates the next row on the next bank. This takes place independent of any user requests, and therefore anticipates a future user request which may (or may not) take place.